Didier Marin and Olivier Sigaud Didier Marin (PhD candidate in Robotics) and Olivier Sigaud (Professor in Computer Science) are with: Universit´e Pierre et Marie Curie Institut des Systémes Intelligents et de Robotique - CNRS UMR 7222 Pyramide Tour 55 - Boîte Courrier 173 4 Place Jussieu, 75252 Paris CEDEX 5, France Contact: firstname.name@isir.upmc.fr
$57,*2 &,(17õ),&2 UREËWLFD
Toward Fast and Adaptive Optimal Control Policies for Robots: A Direct Policy Search Approach ABSTRACT Optimal control methods are generally too expensive to be applied on-line and in real-time to the control of robots. An alternative method consists in tuning a parametrized reactive controller so that it converges to optimal behavior. In this paper we present such a method based on the “direct Policy Search” paradigm to get a cost-efficient control policy for a simulated two degrees-of-freedom planar arm actuated by six muscles. We learn a parametric controller from demonstration using a few near-optimal trajectories. Then we tune the parameters of this controller using two versions of a CrossEntropy Policy Search method that we compare. Finally, we show that the resulting controller is 20000 times faster than an optimal control method producing the same trajectories.
I. INTRODUCTION The mission of robots is changing deeply. In contrast with factory robots always repeating the same task in a perfectly known environment, service robots will have to deal with complex tasks in the presence of humans, while being subject to many unforeseen perturbations. As a result of this evolution, a whole set of new control principles is needed. Among such principles, the study of Human Motor Control (HMC) suggests to call upon optimality and adaptation. However, Optimal Control (OC) methods are generally too expensive to be applied on-line and in real-time to the control of robots. A straightforward solution to this cost problem that also comes with the benefits of continuous adaptation consists in calling upon incremental, stochastic optimization methods to improve the behavior of the system all along its lifetime through its interactions with its environ-
ment. This generates intensive research and, in particular, the direct Policy Search methods are providing more and more interesting results (e.g. [7], [8], [6], [1]). Since such methods are generally sensitive to local minima problems, the optimization process is generally preceded by a Learning from Demonstration (LfD) stage that drives the process to the preferred local optimum. In [9], the potential of such an approach was demonstrated through a simple reaching experiment with a 2D arm controlled by 6 muscles. An OC method based on a computationally expensive variational calculus process was replaced by the combination of two adaptive components. First, a parametric controller was learned from demonstration using a few nearoptimal trajectories, but the resulting policy was suboptimal. Thus, in a second step, the parametric controller was improved by a stochastic optimization process acting on the parameters of the controller. However, the empirical study presented in [9] showed that, despite a good generalization capability and global improvement in performance, the stochastic optimization process was detrimental to performance in the area where the initial controller learned from demonstration was already nearly optimal. In this paper, we focus on this specific issue. We show that the global optimization can be replaced by a more local approach that only acts where the performance must be improved. The paper is organized as follows. In Section II, we present our LfD and stochastic optimization methods, together with some related work. In Section III, we present the design of the experiments. Results of the comparison between the
global method and its local counterpart are given in Section IV. Finally, Section V summarizes the results and presents the perspectives of this work.
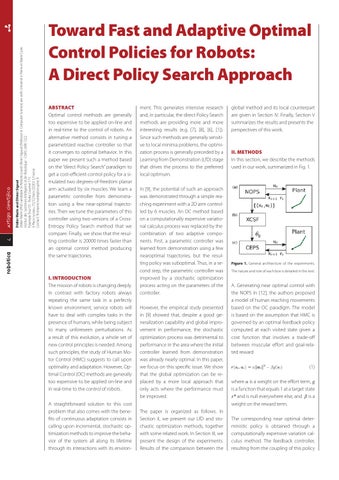
II. METHODS In this section, we describe the methods used in our work, summarized in Fig. 1.
Figure 1. General architecture of the experiments. The nature and role of each box is detailed in the text.
A. Generating near optimal control with the NOPS In [12], the authors proposed a model of human reaching movements based on the OC paradigm. The model is based on the assumption that HMC is governed by an optimal feedback policy computed at each visited state given a cost function that involves a trade-off between muscular effort and goal-related reward (1) where Į is a weight on the effort term, J is a function that equals 1 at a target state V and is null everywhere else, and ȕ is a weight on the reward term. The corresponding near optimal deterministic policy is obtained through a computationally expensive variation calculus method. The feedback controller, resulting from the coupling of this policy
PUB
ACKNOWLEDGMENTS This work was supported by the Ambient Assisted Living Joint Programme of the European Union and the National Innovation Office (DOMEO-AAL-2008-1-159), more at http://www.aal-domeo.eu.
REFERENCES [1]
J. Buchli, F. Stulp, E. Theodorou, and S. Schaal. Learning variable impedance control. The International Journal of Robotics Research, 30(7):820–833, 2011;
[2]
M. V. Butz, D. E. Goldberg, and P.-L. Lanzi. Computational Complexity of the XCS Classifier System. Foundations of Learning Classifier Systems, 51:91–125, 2005;
[3]
M. V. Butz and O. Herbort. Context-dependent predictions and cognitive arm control with XCSF. In Proceedings of the 10th annual conference on Genetic and evolutionary computation, pages 1357–1364. ACM New York, NY, USA, 2008;
[4]
M. V. Butz, T. Kovacs, P. L. Lanzi, and S. W. Wilson. Toward a theory of generalization and learning in XCS. IEEE Transactions on Evolutionary Computation, 8(1):28–46, 2004;
[5]
V. Heidrich-Meisner and C. Igel. Similarities and differences between policy gradient methods and evolution strategies. In Proceedings of the 16th European Symposium on Artificial Neural Networks (ESANN). Citeseer, 2008;
[6]
S. Ivaldi, M. Fumagalli, F. Nori, M. Baglietto, G. Metta, and G. Sandini. Approximate optimal control for reaching and trajectory planning in a humanoid robot. In Intelligent Robots and Systems (IROS), 2010 IEEE/RSJ International Conference on, pages 1290–1296. IEEE, 2010;
[7]
J. Kober and J. Peters. Policy search for motor primitives in robotics. Advances in Neural Information Processing Systems (NIPS), pages 1–8, 2008;
[8]
P. Kormushev, S. Calinon, and D. G. Caldwell. Robot Motor Skill Coordination with EM-based Reinforcement Learning. In Proc. of IEEE/RSJ Intl Conf. on Intelligent Robots and Systems (IROS-2010), 2010;
[9]
D. Marin, J. Decock, L. Rigoux, and O. Sigaud. Learning costefficient control policies with xcsf: generalization capabilities and further improvement. In Proceedings of the 13th annual Conference on Genetic and Evolutionary Computation, pages 1235–1242. ACM, 2011;
[10] V. Pasqui, L. Saint-Bauzel, and O. Sigaud. Characterization of a least effort usercentered trajectory for sit-to-stand assistance user-centered trajectory for sitto-stand assistance. In Proceedings of the Iutam Symposium on Dynamics Modeling and Interaction Control in Virtual and Real Environments, pages 196–203. IUTAM, june 2010; [11] J. Peters and S. Schaal. Reinforcement learning of motor skills with policy gradients. Neural networks: the official journal of the International Neural Network Society, 21(4):682–97, 2008; [12] L. Rigoux, O. Sigaud, A. Terekhov, and E. Guigon. Movement duration as an emergent property of reward directed motor control. In Proceedings of the Annual Symposium Advances in Computational Motor Control, 2010; [13] R. Y. Rubinstein. Optimization of computer simulation models with rare events. European Journal of Operational Research, 99(1):89–112, 1997; [14] R. Y. Rubinstein. The cross-entropy method for combinatorial and continuous optimization. Methodology and Computing in Applied Probability, 1(2):127–190, 1999; [15] C. Sala¨un, V. Padois, and O. Sigaud. Control of redundant robots using learned models: an operational space control approach. In Proceedings of the IEEE/RSJ International Conference on Intelligent Robots and Systems (IROS), pages 878–885, 2009; [16] O. Sigaud and S. Wilson. Learning classifier systems: a survey. Soft Computing-A Fusion of Foundations, Methodologies and Applications, 11(11):1065–1078, 2007; [17] P. Stalph, J. Rubinsztajn, O. Sigaud, and M. Butz. A Comparative Study: Function Approximation with LWPR and XCSF. In Proceedings of the 12th annual conference on Genetic and evolutionary computation, pages 1863–1870, 2010; [18] P. O. Stalph and M. V. Butz. Documentation of JavaXCSF. Technical report, COBOSLAB, 2009; [19] E. Theodorou, J. Buchli, and S. Schaal. Reinforcement learning of motor skills in high dimensions: a path integral approach. In International Conference on Robotics and Automation, pages 2397–2403. IEEE, 2010; [20] S. W. Wilson. Classifier Fitness Based on Accuracy. Evolutionary Computation, 3(2):149–175, 1995; [21] S. W. Wilson. Function approximation with a classifier system. In Proceedings of the Genetic and Evolutionary Computation Conference (GECCO-2001), pages 974–981, San Francisco, California, USA, 2001. Morgan Kaufmann; [22] S. W. Wilson. Classifiers that Approximate Functions. Natural Computing, 1(23):211–234, 2002.