2. Behavioural Analysis UserBehaviorAnalysis(UBA)isthedisciplinarymannerof readingbehaviorofthatperson.Inanoperationalmannerit is able to be defined as, essentially amassing records, monitoring the obtained records, processing that information for analyzing. The required records sets for work is accumulated from the customers that's history of browsed records are saved in separate documents, databases,directoriesorstatisticslogfilesandsoforth.The cause of this collection of datasets is a technique to offer favoredparametersandfromthisfactsit'sfarveryeasyto buildusableanddependablefashionstheuser.Indifferent phrases,itwillexactlyclassifytheusergroupandcorrectly represent the users. For instance, these days the Internet surfing has emerge as maximum privileged space for this sort of software. Indeed, these days technologies are so grownupineachaspectsi.e,inordertoacquirerecordsand then exploit the prevailing, past and future behavior of individualcustomers.The3pillarsofUBAare:Analysisof facts,integrationofrecordsandillustrationofinformation. Themaximumtoughundertakingconfrontedisinanalyzing andprocessingthebigquantityofinformation.Theanalysis ofUBAinhavetobespeedyinpre processinghugestatistics oftheusers.AnddecidedondevelopedMLalgorithmsmust besuitabletoclassifytheusers.Therefore,MachineLearning algorithmsoughttoruninrealtime,ifyouwanttobeeasily havingaccesstotocompleteinformationsets.
3. DATASETS COLLECTION
1. USER BEHAVIOR ANALYSIS AND PREDICTION
Thedatasetseriesisexecutedviaananonymizedviewingof internetsitethroughthatspecificusers.Fromsearchengine weareabletoknowthewhathasbeenbrowsedpreviously. There are many browsing history tools which collects browsedfactsautomaticallyasshownintable1.Amongthe onessomeareopensupplyandsomearecertifiedversion equipment.Differentequipmenthavedistinctivefunctionsto collect information. So we observed tool named surfing historyviewtoolthatisappropriateforthework.
The consumer version is a illustration of single user or it could be a group of a couple of customers in gadget. This evolvedmodelincludesasetofstatistics/parameterswhich are consultant of the person’s preceding conduct. The improvement of consumer model starts with machine designingagoodwaytobeamassingalloftheinformation records wanted for representing the users. The real time data obtained from surfing device can be used to deeply recognize the behaviour of an user [4]. The model development is achieved primarily based on positive functions and parameters which tells about consumer conduct, in which the consumer is maximum inquisitive aboutsurfingthedata.Thesebrowsedfactsmaybeacquired thru numerous packages from the web. From these developed model end result we will recognize consumer hobbyinadvanceandthenitisabletosmoothtoprovide personalizedofferings.Supposeifanydataismissing,that maybewithoutproblemsretrieved.Andfuturesportsand behaviourscanbepredicted
Fromthepastmanyyears, analysisofconsumerhasbeen targetedontheacuteeffortsinadvertisingpackages,buying goal of some online shoppers and so forth. Obviously, the goal of this paintings is to undertake green and a few different new specific advertising strategies. And those techniques are based on actual time datasets. That is recordeddatasetfactsfromthesystems.Whichconsistsof thepast/precedingsportsofthatcustomersorclient.Sothis canbedefinedasastatistics basedbehavioralevaluation,it because evaluation completed on recorded facts records. This analysis has found its significance in detecting fraud informationandfightingagainstfraudandsoforth.Sonow, thisisn'talwaysthatmarvel tolookbehavioranalysiscan decorate facts communique era, hit upon internal threats likefocusedattack,boostupsomerepetitiveduties,adapt software program's to the customers so organize more correctlymanufacturingtoolsetc.
International Research Journal of Engineering and Technology (IRJET) e ISSN: 2395 0056 Volume: 09 Issue: 01 | Jan 2022 www.irjet.net p ISSN: 2395 0072 © 2022, IRJET | Impact Factor value: 7.529 | ISO 9001:2008 Certified Journal | Page687 Detection of Behavior using Machine Learning Sri Sahith Reddy Kuncharam1 , Sambhav Jain2 , Jash Nimesh Dharia3 , Anish Chintamaneni4 , Jayanth Guduru5 , Harshavardhan Neelathi6 *** Abstract DuetoCOVID 19,there'safastboomwithinso that result can be more correct in pre processing and prediction. Here, Pre processing covered challenges along withhandlingofhugefacts.Sometimesthatcannotinshape intothememory.Severalpotentialstudieschallengeshas beenconfrontedinrunningwithML/DL[1].Inthispaper,we addresstheaboveissuesdiscussedbymeansofgathering actual time datasets. For this, we made an experimental installationwith20computersystemsinalabandaskedall thestudentstobrowseforanhourwithnonemonitoring. Latertheseactualtimedatasetshavebeenaccumulatedfrom browsed history of diverse websites. Support vector machine(SVM).Inordertoanalysesandexpectthefuture utilization,thepredictionofconsumerconductisachieved theuseofMachinelearning(ML)method.In whicha hard andfastofdiversefeaturesareextractedfromdatasets,then theversionforpredictionisevolved.Themodelistrained basedtotallyoneighty%ofeducationand20%ofchecking out80%approach.Thesealgorithmsaremaximumsuitable and gave exceptional bring about the survey. The User BehaviorAnalysis(UBA)andpredictionispredictedwiththe aid of invoking advanced model in python programming. Andthoseoutcomesareincomparisonwithallofthethee algorithms.

ManyoftheMLmethodshasshownthepromisingresults required for the predicting user behavior on internet site. From the excessive level model of facts you may create course for modeling for predicting person behavior. A excessive stage information cab be constructed on how exactlyrecords propagates over time. In thisvisit time i.E periodspentandvarietyoftimevisitsmadetothatbrowser havebecomeusefulapproachinunderstandingtheUBAin Web. And additionally by way of taking various different functionsfromobtainedstatisticswecangetmoredistinct view of consumer conduct[6]. The function parametric primarilybasedtechniqueforgrowingamodelwillprovide aextraprecisemodelwithsuitableaccuracy.
GeneralstepsforPredictinguserconductbasedoninternet browsingrecordsare
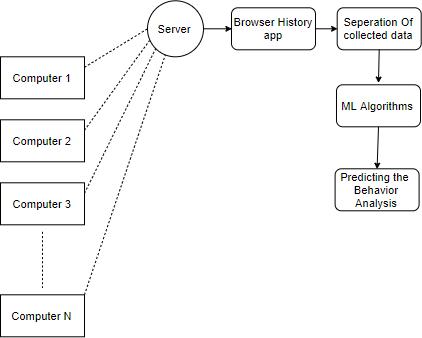
Step 3: Now users are allowed freely for browsing information in their very own hobby, the surfing is performedforsuretimeduration.Nextstepistogatherthe browsed statistics from the application set up inside the Stepdevice4: The accrued browsed statistics is given to gadget masteringalgorithms.Thealgorithmsdotheclassbasedon comparableinformationbrowsed.Andtheonesaregrouped andSteplabeled.5:Thus, all features are classified and then we will predicttheuserbehaviorevaluationandexaminewithML algorithms.
Step 2: Then next step is to down load and deploy web surfing records programs in each of the computers i.E BrowsingHistoryView.
International Research Journal of Engineering and Technology (IRJET) e ISSN: 2395 0056 Volume: 09 Issue: 01 | Jan 2022 www.irjet.net p ISSN: 2395 0072 © 2022, IRJET | Impact Factor value: 7.529 | ISO 9001:2008 Certified Journal | Page688 no.Sl Tool Availability Advantages Disadvantages 1 Time web[10]your Freesource Best for graphchromeGoogletimebar Does not support other websites 2 watch[10]Activity Freesource extensionsforAvailableMozilla Not good for Google chrome and other websites 3 Time[10]Rescue Not free source completeKeeps It is not free source track of all activitiesonline 4 View[9]HistoryBrowsing Freesource Reads the historydata from 4 Browsing.webdifferent sometimes it bloat the 'Visit Count' number only explorer.internetfor Each log of the browsed information includes person information like user identity (ID), Uniform Resource Locator(URL),Title,VisitTime,VisitCount,WebBrowser, URLLength,TypedCount,HistoryFile,Duration,RecordId. Nowbywayofcrawlingandparsingthetypeofstatisticshas been browsed, we were given facts regarding URL, name, typedmatterandregardedinternetsitefromtherespective website browsing and content material providers. Specifically,we'vegotlabeledsurfinginto5differenttypes. Suchassocialmediabrowsing,academicpurpose,shopping, information,entertainmentandothermotive.Theoneofa kind content carriers in internet has very own way of naming conventions titles and different parameters. For example,insomeofthelogswedeterminedthatatthestart offactsthecontentissuer’scallisembeddedwiththetitles of the browsed websites. Then from these naming conventions, the manual modification is accomplished to differentiatetitlesandinternetsite.Bydifferentiatingthose parameter,mixingofparametersareprevented.Whichlater classify the statistics correctly and effectively. Figure 2 is capturedviewofhowstatisticsisaccumulated.Thestatistics isreceivedissavedinexcelorcommaseparatedvalues(csv) file.Thisisachievedasitisstraightforwardtoinvokethese documentslaterinprogramming. Thebrowsedrecordsisaccruedatnumeroustimeperiodi.E atmorning,afternoonandnighttime.Thisisdoneduetothe fact surfing facts varies occasionally. For example, some customers are interested in information sites on the first light,afewusermightbrowselookatrelatedwebsitesand onthenighttimepersonmaybrowsesocialmedianetworks. Thesurfingstatisticsvariesuserfromtoperson.So,forour work we've taken browsed statistics from morning to nighttime.
A.Machine Learning Algorithms For Uba
Step1: Arrange and setup nearly five 10 in number of computerswithinthebranch.Andthoseneedtobewiththe same configurations like hard disk garage(RAM, ROM), Power,Speedofthedeviceetc.
4 METHODOLOGY
Figure3.showscompleteprocessinvolvedinclassifying
k clustering is an unmanaged approach of ML method in clusteringtherecords.Thisclusteringobjectivestofindout ok widevarietyofclustersfromtheenterfacts.Where ok refers to general number of clusters that need to be generatedbysetofrulesforthatenterdatasets.Thismethod ofclusteringislargelycalculatedandcarriedoutbymeansof iteratively allocating every statistics point to the diverse clusters. These statistics points are allocated to one in all okay clusters of overall clusters according to the and minimal distance among the points and additionally primarily based on diverse functions. To get the closing result of clustering repeatedly trained and examined. The inputs of the algorithm are only the datasets and the k clusters.Firstly,thekcentroidsareexpectedthroughWithin clustersumofsquares(wcss)orotherapproach.Andthen every of the sample in statistics is assigned to its one in every of its closest cluster. This assigning is completed estimating centroids. Which is calculated the usage of squared Euclidean distance among the all the points. Secondly,oncealloftherecordsfactorsofthesamplesare assigned to a distinctive cluster, and on the other hand centroids are recalculated via taking mean of all sample values of cluster. The algorithm new release endured to iterate until no sample of the records is left. The overall
(iii) Support vector machine (SVM)
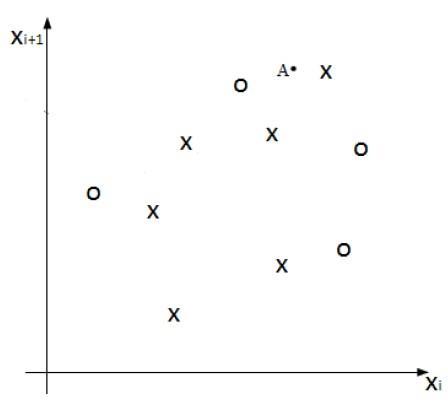
Supportvectordeviceisannon probabilisticclassifier.The assigning of labels for prediction is achieved with SVM version. Whereit predicts intooneorother category.The SVM builds a boundary among lots of data points in n dimensional space. Here n represents the total range of capabilities. Considering a SVM classifier, the boundary amonganyofthe2lessonscanbetakenintoconsideration bestaftereducationthisSVMclassifier.Here uniqueclasses arelabeledascrossesandcircles.Supposeforthe new'n' dimensionalfactorifpointsliesaboveboundarylinethenit is labeled and categorized as 'go' and a 'circles' if no longer[8].Fromthedetermine5weseethatfactorsA,Band Careclassifiedas`crosses'.Thisisbecausethey'reabovethe boundarydegree.
International Research Journal of Engineering and Technology (IRJET) e ISSN: 2395 0056 Volume: 09 Issue: 01 | Jan 2022 www.irjet.net p ISSN: 2395 0072 © 2022, IRJET | Impact Factor value: 7.529 | ISO 9001:2008 Certified Journal | Page689
(i) K nearest Neighbor (ok NN)
(ii) Naives Bayesian theorem
(iv) ok clustering
The main idea of this K NN strategies is to pick out okay neighboringvectorsforalloftheinputvectors.Letusrecall xasanentervector.Forselectingneighboringvectorsofthe enter vectors is taken as distance metrics between the numerous facts factors of input vectors. Here for locating minimumdistance,Euclideandistancecalculatingapproach is implemented. Now next step is to locate the similarity measure and then examine all of the vectors. From the outcomesofsimilaritydegreewegaintheclosestKbuddies. In case of calculating the Euclidean area distance, the similaritydegreei.E,S(p,q)between vectorspandqareto betakenintoconsideration.
The problem system in predicting behavior of user in ML terminology cab be naturally carried out in a trustworthy manner[6].Here,theproblemmaybeformulatedasatype venture. The principal aim is to predict the outcome outcomesofconsumer.Fornewunitsof`check'samplesone should construct a predictive version M. From developed version we can get accuracy for that model. Some of classifierfashionsareevolvedforourworkwhichgavenice effects.
TheNaivesBayes’theoreminshortexplainsapproximately the opportunity. That is, probability of taking place an incident or event taking the of previous statistics that is related to this event/ incident[7]. For example, network visitors information associated with the attack may be regardedwithDoSassaultstatistics.Therefore,comparing withthecommunitysitevisitorsandassessingthiswithout theunderstandingthebeyondnetworktrafficdatawecan evaluate visitors of the network opportunity the use of Bayes' theorem. A common and green Machine Learning (ML) set of rules based totally on chance calculation is a NaiveBayes(NB)classifier.ThisNBclassifierdoesthetype withtheaidofestimatingopportunityofthedatasets.NBisa commonlyregardedandusedasasupervisedclassifier.This NBclassifierscalculatesposteriorprobabilityforthegiven records after which uses the Bayes' theorem to forecast's that the chance. Which does the feature sets of not categorised examples of NB classifier the ones examples suitsaparticularlabelofNBclassifiers.Nowthinkingabout anintrusiondetectionasinstance,NBisusedasaclassifier to classify this traffic as ordinary or everyday. The advantagesofNBclassifiersarelikeeaseofimplementation, simplicity, applicability to binary and multi magnificence classification,robustnesstoinappropriatecapabilitiesand requirementoflowtraining.AsfromML,theNBstrategies givesaverysimplemethod,withclearsemantics,alsoforthe usageof,forrepresenting,andforknow howofmastering probability. This NB classifier aim is to accurately are expectingtheclassoftakealookattimes.
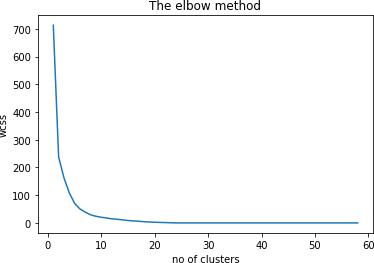
In this clustering method the statistics sample want to be clustered in unique ok cluster. The price of ok can be estimated by using WCSS method. This estimation calculation is executed using Euclidian distance this of sample.Figure6showsthegraphicalrelationshipbetween withinclustersumofsquares(WCSS)andrangeofclusters. Then select the number of clusters where the alternate in WCSSstartstodegreeoff(elbowtechnique).Thisisresultant graphacquiredforourdatasets.
The Unsupervised ML methods have many packages in safetydomain. (v). EXPERIMENTAL RESULTS
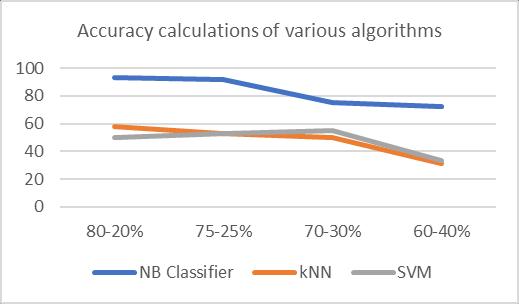
From comparison table 2 we can say best ML for our datasetisNaivesBayesclassifier.Thisisbecauseitisgiving accuracyabout93.33% From the discern 8, it's far observed that for all the proportion of statistics units, NB is giving the best overall performancewhileascomparedwiththeotheralgorithms.
Table 2: Comparisontable Algorithm 20%80 25%75 30%70 40%60 ClassifierNB %93.33 91.66% 75.11% 72.22% KNN 58% 53% 50% 31% SVM 50% 53% 55% 33.3%
performanceandaccuracyofclusteringislessuniquethan those of the opposite supervised leaning strategies. In generatingacategorizedrecordsit'smileshardtogenerate. thisexample
unsupervisedalgorithmsareappropriate.
TheMLalgorithmswereappliedthinkingaboutanumberof the capabilities. Firstly, the real time datasets which is needed to our work is collected from consumer personal computers are hooked up with browser history tool. Now datasets are rearranged and modified. These datasets are divided as trying out and education units (20 80%) technique.Theeighty%schoolingiseducatetheevolvedML algorithm and 20% trying out is to test output results as soonasclassificationisperformed
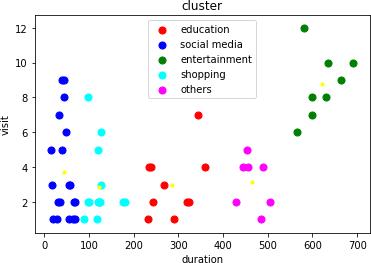
From the graph and end result we can say that that user maximum interested by browsing data that is related to wonderfulsites.Thisisduetothefactrangeoftimevisitand periodoftimehespentismoreincomparisontodifferent clusters.
D. SVM ThelastsetofrulesselectedfromthesurveyisSVM.Sofor thissetofrulessamesortoftechniqueisobserved.Theend resultgotfromthissetofrulesistabulatedindesk2. Inthissetofrulesweweregivenniceendresultat70 30% educationtechniqueapproximatelyfiftyfive%ofaccuracy.
In this NB classifier set of rules datasets are skilled and examinedatexclusiveatspecialfrequencies.Theadvanced NB classifier algorithms outcomes are tabulated as table 2.These are the accuracy performance effects at diverse trainingsetmethod.Theclassifiergotappropriateaccuracy at75 25%trainingalgorithmi.Eapproximately93.33%.
International Research Journal of Engineering and Technology (IRJET) e ISSN: 2395 0056 Volume: 09 Issue: 01 | Jan 2022 www.irjet.net p ISSN: 2395 0072 © 2022, IRJET | Impact Factor value: 7.529 | ISO 9001:2008 Certified Journal | Page690
5. CONCLUSIONS In these paintings, with consumer browsed statistics are acquired from browsing records viewing device. Here we model browsed statistics in connection with social community,enjoymentplatform,othersandsoon.Through realinformationevaluation,welookatconsumerwherein that individual is maximum fascinated. So we developed someofMLsetofrulestocategoriserecords.TheProposed fashionsareusedanalyzeandareexpectingtheUBfromthe
B. Naives Classifier
C. KNN Second algorithm selected for classification is kNN set of rules, for this also equal technique is carried out for educationandtryingout.Theaccuracyresultreceivedare tabulatedintable2. Inthissetofrulesgotqualityendresultat80 20%training techniqueapproximatelyfiftyeight%ofaccuracy.
So,in
A. Okay NN clustering
International Research Journal of Engineering and Technology (IRJET) e ISSN: 2395 0056 Volume: 09 Issue: 01 | Jan 2022 www.irjet.net p ISSN: 2395 0072 © 2022, IRJET | Impact Factor value: 7.529 | ISO 9001:2008 Certified Journal | Page691 datasetafterwhichcalculatetheaccuracyofeveryalgorithm advanced. The set of rules selected here are KNN, NB classifier,SVMandforclusteringtherecordskwayisused. Amongtheseadvancedalgorithms,wegotrightresultforNB classifier.Itgaveanaccuracyapproximately93%.Fromthis weareabletoconcludethatNaivesBayesClassifieristhe first rateamongstallotheralgorithmsevolvedandwegot first rateeffectsforthisworkfinished. Infutureweareabletobetryingtopredictandanalyzeby usingthinkingaboutdifferentparameterforthepaintings. Andwewilltrytocomparewithdifferentalgorithmstoo.In futuredifferentalgorithmsmayadditionallysupplyhigher accuracyoverallperformancethanNBClassifier. 6. REFERENCES [1]. M. Callara and P. Wira, "User Behavior Analysis with Machine Learning Techniques in Cloud Computing Architectures,"inthepreceedingofInternationalConference onAppliedSmartSystems(ICASS),Medea,Algeria,2018,pp. 1 [2]6.H.Yan,C.Yang,D.Yu,Y.Li,D.JinandD.Chiu,"Multi site User Behavior Modeling and Its Application in Video Recommendation,"inIEEETransactionsonKnowledgeand [3].Ladekar,DataEngineering.Ashwini, Pooja Pawar, Dhanashree Raikar and Jayashree Chaudhari. “Web Log based Analysis of User's BrowsingBehavior.”(2017). prediction[6](ICCTIDE'16),Computingmining,"behavior[5]10.5120/ijca2016909228.InternationalWeb[4]R.,Virendra&V.,Govind,"PredictionofUserBehaviorusingloginWebUsageMining"intheproceedingsofJournalofComputerApplications.139.47.V.AnithaandP.Isakki,"AsurveyonpredictinguserbasedonwebserverlogfilesinawebusageintheproceedingInternationalConferenceonTechnologiesandIntelligentDataEngineeringKovilpatti,2016,pp.14.Sisodia,D.S.,Khandal,V.,&Singhal,R.(2018).Fastofwebuserbrowsingbehavioursusingmost interestingpatterns.JournalofInformationScience,44(1),74 90.