
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
ADITYA BHANUSHALI, SHUBHAM SOMANI, ADITYA KULSHRESTHA, SUBODH SAHU
Abstract -Theexponentialproliferationoflargelanguagemodels(LLMs)fromdiversevendors(e.g.,OpenAI,Anthropic, Google) has generated an acute need for standardized, objective comparative evaluation. Conventional methods, often reliant on fragmented industry benchmarks or subjective, costly human assessment, fail to provide a holistic view necessaryforenterprisedeployment.Thisfragmentedlandscape,compoundedbychallengesinherentinevaluatingopenended,generativeoutputs,necessitatesaunifiedsolution.Thisstudypresentstheconceptualarchitectureof
Cogniview, an API-agnostic platform designed to standardize model interaction and provide multi-dimensional assessment across Capability, Operational Efficiency, and Alignment/Safety criteria. The methodology relies on a layered design featuring an API Abstraction Layer for output normalization and a Hybrid Validation Loop that integrates automated LLM-as-a-Judge scoring with critical Human-in-the-Loop (HITL) governance for bias auditing and criteria refinement. Conceptual results, analyzed via a Multi-Criteria Decision Analysis (MCDA) weighted scorecard, demonstrate Cogniview'scapacitytoilluminateessentialtrade-offsbetweenmodelperformance(e.g.,MMLU/HumanEval),operational fitness(latencyandcost),andsafetyrisks(hallucinationrate,adversarial robustness).Cogniview offers anindispensable frameworkforMLOpsteamsseekingdata-drivenguidanceinselectinganddeployingtheoptimalLLMforspecificbusiness imperatives.
Keywords: LLM Evaluation, Unified Platform, Generative AI, Multi-Criteria Analysis, LLM-as-a-Judge, Factual Consistency, MLOps.
1.1 The Evolving Landscape of Generative AI Proliferation
The digital media ecosystem has undergone a significant transformation, moving beyond conventional content classification challenges such as fake news detection using traditional machine learning classifiers like Logistic Regression to the complexities introduced by generative content. The widespread availability of powerful foundational models, including offerings from OpenAI (GPT), Google (Gemini), and Anthropic (Claude), has democratized high-level artificial intelligence capabilities. This rapid advancement, marked by frequent releases of increasingly sophisticated systemslikeGPT-5,hascreatedadynamicandcomplexselectionenvironmentfordevelopersandlargeenterprises.
Thisproliferationhasledtoamarketcharacterizedbydiversemodelarchitectures,heterogeneousAPIs,andvariedpricing structures.With wellover25modelsaccessiblethroughsomeplatforms,includingthosefromMeta,Mistral,andAlibaba, organizations face significant fragmentation and mounting operational costs if they choose to access top-tier models independently.Thesheervolumeand velocityofinnovationnecessitatecontinuous,rigorousevaluation,makingtheneed forastandardizedcomparativeframeworkacriticalindustryimperative.
1.2 The Imperative for Standardized, Unified Comparative Analysis
For enterprises, objective model selection is vital for resource management, performance assurance, and regulatory compliance.Thecurrentpracticeofrelyingonmultiple,disparateevaluationsoftenyieldsincomparablemetrics.Tobridge thegapbetweennumerousmodelchoicesandstrategicdeploymentdecisions,asingle,objectiveframeworkisrequired onethatenablesadirect,apples-to-applescomparisonacrossdiversemodelofferings.
The realization of this need has spurred the development of specialized evaluation services, such as those integrated within enterprise AI platforms like Google’s Vertex AI. These platforms aim to manage the complexity of API integration andprovideacentralizedevaluationmechanism.However,comprehensivecomparabilityisobstructedwhenassessments areconductedusingfragmentedindustrybenchmarksuites(e.g.,GLUEforlanguagetasks,ImageNetforcomputervision) or by relying solely on internal, custom-developed tests. Such fragmented analysis lacks the consistent comparability requiredforobjectivevendorselectionandrobustmodelvalidation.
1.3 Challenges Inherited from Traditional ML and LLM-Specific Evaluation
Evaluating generative AI presents challenges fundamentally different from those encountered in traditional binary classification tasks such as the fake news detection detailed in prior work where performance is measured against a
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
staticgroundtruthusingmetricslikeF1-scoreandaccuracy.Incontrast,generativemodelsproduceopen-ended,diverse outputsthatdemandnuancedassessmentmethods.
The most reliable evaluation traditionally involves human assessment, capturing qualitative aspects like creativity, tone, and coherence. However, this "vibe-check-based evaluation" is inherently subjective, prone to evaluator bias, and tremendouslyexpensiveandtime-consuming,particularlywhencoordinatingandcompensatingcrowdworkers.Thislack ofscalabilitypreventsreal-time,large-scalequalitymonitoringinMLOpspipelines.
Purelystatisticalmetrics,derivedfromstringmatching(e.g.,BLEUandROUGE),are fastandreproducible.Yet,theyoften fallshortbecausetheypenalizesyntacticvariationevenwhenthegeneratedoutputissemanticallyequivalentorfactually accurate. ROUGE, which prioritizes recall based on the longest common subsequence , is useful for determining content coverage but still fails to fully grasp semantic nuance, making it an unreliable sole indicator of quality in open-ended contexts.
1.3.3
A significant concern surrounds the reliability of widely used academic tests, such as the Massive Multitask Language Understanding (MMLU) benchmark. Models are increasingly likely to encounter these questions during pre-training, leading to score inflation that measures memorization rather than true generalization ability. Furthermore, even minor formatting changes such as substituting parentheses (A) with brackets [A] for multiple-choice options can trigger accuracyswingsofapproximately5%onthesebenchmarks.Thisinherentfragilitysuggeststhatfixed,staticbenchmarks are inadequate proxies for model capabilities in real-world applications. The operational necessity of evaluation has therefore expanded beyond academicscores.Metricslikelatency(responsespeed)andthroughput (processing capacity) havebecomecriticaldecisionfactorsformeetingServiceLevelAgreements(SLAs)indeploymentenvironments.
The Cogniview platform is proposed as a unified, three-layered framework to address these systemic challenges. It integratesAPIabstractionforinput/outputstandardization,efficientparallelexecutionforoperationalmeasurement,and amulti-metriccore.
The platform’s core contribution is the consolidation of traditional capability benchmarks with vital, real-world operational factors (latency, cost) and critical ethical and safety evaluations (hallucination rate, bias, adversarial robustness). By utilizing a sophisticated Multi-Criteria Decision Analysis (MCDA) framework, Cogniview provides MLOps teams with a weighted, use-case specific score, enabling the objective selection of the optimal model for deployment, therebyadvancingresponsibleanddata-drivenAIgovernance.
The remainder of this paper is structured as follows: Section II reviews related work, contrasting current evaluation paradigms with the need for multi-dimensional assessment. Section III details the methodological architecture of the Cogniview platform, outlining the abstraction layer, execution engine, and integrated evaluation protocols. Section IV presents conceptual results derived from the platform, illustrating its interpretive and comparative utility through synthesized scorecards and case studies. Finally, Section V concludes the research and suggests avenues for future investigation.
2.1 Evolution of AI Evaluation Benchmarks and Frameworks
Historically,AIevaluationcenteredonstandardized,staticdatasetssuchasGLUEandSQuADtomeasuremodelproficiency inspecificnaturallanguageprocessing(NLP)tasksandclassification.Asmodelsbecamebroaderincapability,frameworks evolvedtoattemptamorecomprehensiveview.
TheHolistic EvaluationofLanguageModels(HELM)andOpenLanguageModel EvaluationStandards(OLMES) represent significant research efforts toward establishing robust, reproducible, and standardized evaluation criteria across numerousmodelsanddiversedomains.Furthermore,evaluationhasshiftedtowardassessingcapabilitiesineconomically
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
relevant, complex, and specialized real-world scenarios. Examples include HumanEval for coding performance , SWEBenchforsoftwareengineeringbug-fixing,andGDPval,whichmeasuresperformanceacross44occupationsselectedfrom topU.S.industries.Thisprogressionhighlightsacleartrend:evaluationmustsimulatereal-worldoccupationalcomplexity togenuinelygaugeamodel’sutility,ratherthansimplymeasuringabstractacademicproficiency.
The inherent difficulty in assessing generative quality has driven the adoption of hybrid metrics. While fast, referencebased statistical metrics (BLEU, ROUGE) remain common, their limitations are widely acknowledged; they lack semantic understanding,makingthempoorjudgesofqualityinopen-endedcontexts.
For highly creative fields, such as image or text generation, quality assessment necessitates a careful balance between quantitative metrics and subjective human judgment. In generative image evaluation, for instance, metrics such as the Frechet Inception Distance (FID) are used to measure the similarity between the distributions of real and generated images. A low FID score indicates strong statistical similarity, yet qualitative assessment remains crucial for capturing creativity,style,andnuancedhumanpreference.Thisgapunderscorestheneedforplatformsthatcanseamlesslycombine deterministicstatisticalanalysiswithsubjectivehumaninterpretation.
Thechallengeofmodel comparisonhasled tothe emergenceoftwoprimarytypes ofplatforms:commercialaggregators andenterpriseMLOpssolutions.
Commercialaggregators,suchasPoe.comandYou.com,offeruser-facinginterfaceswhereindividualscaninteractwithand compare multiple models (e.g., GPT-4.5, Claude 3.7) simultaneously. These platforms offer convenience but typically rely on proprietary access and often provide simplified, preference-based scores rather than deep, multi-criteria technical evaluations.
Intheenterprisespace,integratedsolutionslikeVertexAIEvaluationandAzureAIFoundryoffercomprehensiveservices spanning fine-tuning, evaluation, and deployment. These tools enable valuable capabilities, including tracking evaluation resultsusingsystemslikeMLflowandNeptune.ai,andfacilitatingpairwisecomparisons.
Despite these developments, a gap persists. No existing platform provides a unified pipeline capable of simultaneously abstracting dozens of vendor APIs, computing granular operational costs, systematically evaluating alignment risk, and synthesizing these diverse data points via a configurable weighted scorecard. The complexity of comparing models on operational efficiency is significant; for real-time applications, a model with slightly lower MMLU but vastly superior latency may be the optimal choice. This necessitates a framework that elevates operational metrics (latency, cost) to the samelevelofimportanceascognitiveperformance.
Toovercomethescalabilitylimitationsandcostofpurelyhumanevaluation,theparadigmofLLM-as-a-Judge(LLM-Judge) has emerged, wherein a powerful language model is used to evaluate the outputs of other generative models. This approachapproximateshumanjudgmentatasignificantlylowercostandhigherspeedthanmanualannotation.
LLM-Judges are flexible, capable of performing both POINTWISE (direct scoring against criteria) and PAIRWISE (ranking two outputs against each other) comparisons. Researchers have developed specialized LLM judges, such as EasyJudge, which are fine-tuned on extensive, multi-scenario datasets with up to 139 evaluation criteria, resulting in precise, multidimensionalassessments.
However, reliance on LLM-Judges is not without challenges. These models inherit social biases from their large training datasets and may lack the transparency required for deployment in critical systems. Furthermore, open-source LLM evaluatorsoftenexhibitweakcorrelationwithhumanjudgments andwithevaluationsconductedbyproprietary,state-ofthe-art judges. This necessitates caution, particularly against over-reliance on LLM-Judge capabilities for automated decision-making in sensitive contexts. For this evaluation technique to be reliable, it must be treated as a supervised, auditablesystem,witharchitecturalsafeguardsensuringhumanreviewprimarilyservestorefinethejudge'scriteriaand auditforinheritedbiases.
2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
The current research highlights a fragmentation in evaluation focus: capability scores (e.g., MMLU) are assessed independentlyfromspeedmetrics(latency/throughput)andsafetymetrics(e.g.,HarmBench,Toxigen).Acomprehensive analysisframework,suchastheCogniviewplatform,mustsynthesizethesedisparatedimensions.Thisrequiresintegrating advanced validation methods (e.g., cross-validation for robust generalizability assessment ), ethical evaluation protocols (including Statistical Parity and Equal Opportunity measures ), and quantitative safety benchmarks (e.g., Hallucination Rate leaderboards ). The fusion of these technical, operational, and ethical criteria provides a holistic assessment frameworksuitableforresponsible,real-worldAIdeployment.
Cogniview is architected as a robust, three-tiered system the Abstraction Layer, the Execution Engine, and the MultiMetric Evaluation Core designed to harmonize the process of comparative model assessment, ensuring flexibility, performanceorchestration,andtransparentmulti-dimensionalscoring.
3.1.1 The API Abstraction and Standardization Layer
This layer is foundational, acting as a buffer that manages interactions with disparate vendor APIs, including those from OpenAI,Anthropic,GoogleCloud,andothermajorproviders.Itsprimary roleistoenforceuniformityindata handling.A standardized prompt format is transmitted to all models, and critically all heterogeneous model outputs are parsed intoasingle,uniformdataschemabeforeevaluationbegins.
The implementation of a rigorous Standardization Protocol is mandatory. This involves normalizing common data fields, such as dates or names, and applying semantic normalization steps. These steps may include removing extraneous whitespace, converting text to lowercase, or validating outputs against strict structural requirements, such as expected JSON output formats. This foundational layer ensures that all downstream comparisons, whether via statistical metrics (like ROUGE) or hybrid validation (LLM-Judge scores), operate on consistent data, thereby establishing the necessary foundation for objective analysis. Any failure to standardize outputs would render cross-model comparisons inherently unreliableorbiasedduetostylisticandstructuralvariations.
3.1.2
The Execution Engine is responsible for managing the parallel execution of the standardized model queries across all selected candidates. Beyond simply routing requests, this component performs critical operational tracking. It precisely measures real-time deployment metrics, including Latency (specifically Time-to-First-Token, or TTFT) and Throughput (tokenspersecond,tps),acrossvaryingrequestloads.
To ensure MLOps readiness, the engine integrates stress testing capabilities, enabling the identification of performance degradationinflection pointsthatoccur whenresources saturateunder peak load.Furthermore, the system incorporates detailed Resource Allocation tracking, monitoring computational consumption per model configuration (e.g., specific hardware or quantization levels). This level of tracking is essential for providing accurate Cost Analysis, comparing the financialimplicationsofdifferentmodelsbasedonactualusagecostspertoken.
The Cogniview platform structures its comprehensive evaluation into three critical domains: Capability, Operational Efficiency,andAlignment/Safety.
3.2.1
Thesemetricsassessthecognitiveabilitiesofthemodels:
Reference-Based Metrics: Quantitativeevaluationofgeneratedtextfidelityusing ROUGE-N,ROUGE-L,andBLEUscores, typically against human-created ground truth answers for tasks like summarization. The platform acknowledges the semanticshortcomingsofthesemetricsbutretainsthemfordeterministic,rapidregressiontesting.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
Logic/Code-Based Metrics: ValidationofprogrammingandstructuralintegrityusingstandardizedtestslikeHumanEval, which assesses function completion, or custom code execution tests that rigorously check the format and logical correctnessofgeneratedcode,adheringtostandardslikeJSONschemaverification.
3.2.2 Operational Efficiency Metrics (The How Fast/Cheap)
Thesemetricsarecrucialfordeploymentdecision-making:
Latency (TTFT): Measures the initial responsiveness, which is vital for interactive applications. Optimizing this metric often involves techniques like model quantization, and comparison against competitive baselines provides essential contextformeetinguserexperiencerequirements.
Throughput (Tokens per Second): Measures the sheer volume processing capacity of the model, critical for large-scale automationandbatchinferencetasks,trackedacrossvaryingtrafficconditionstoidentifybottlenecks.
Cost Analysis: Provides granular data on input and output token pricing per vendor. For instance, comparing a model costing $2.00 per million input tokens against one costing $6.00 per million output tokens reveals the true financial efficiencynecessaryformassive-scaleoperations.
3.2.3 Safety and Alignment Metrics (The Trustworthiness)
Thesemetricsassesstheethicalandsafetyprofileofthemodels:
Hallucination Rate & Factual Consistency: The platform uses specialized evaluation models, such as the Hughes Hallucination Evaluation Model (HHEM-2.1) , to quantify the frequency of generating plausible but unsupported facts. Evaluationmustspecificallytest robustnessagainstreal-worldadversarial userinteractionsbyincorporatingchallenging "in-the-wild" query datasets like HaluEval-Wild. The known behavioral tendency for models to hallucinate because standardaccuracyevaluationsrewardconfidentguessingover admitting uncertaintyrequiresthe platform toimplement measuresthatexplicitlytrackmodeluncertaintyandpenalizeassertive,high-confidencefalsehoods.
Bias and Fairness Metrics: Assessment relies on standard statistical metrics derived from the confusion matrix (True Positives,FalsePositives,etc.).KeymetricsincludeStatisticalParity,whichmeasuresdemographicparity,and
Equal Opportunity (EO).TheEOmetricismathematicallydefined toensurethattheTruePositiveRate(TPR)andFalse PositiveRate(FPR)ofamodelarestatisticallyequivalentacrossprotectedandunprotectedgroups:
EO=½·[(FPₚ/(FPₚ+TNₚ)−FPᵤ/(FPᵤ+TNᵤ))+(TPₚ/(TPₚ+FNₚ)−TPᵤ/(TPᵤ+FNᵤ))] (1)
Equation (1): Equal Opportunity (EO) Fairness Metric where p and u denote protected and unprotected groups, respectively. This metric is essential for assessing fairness in high-stakesdomainslikeriskscoringorpredictivepolicing.
Adversarial Robustness: This is quantified by measuring the Attack Success Rate (ASR) of attacks designed to elicit harmfulcontent.UtilizingbenchmarkslikeHarmBenchandToxigen,theplatformtracksmodelresistanceacrosssemantic categories, including cybercrime, chemical/biological weapons, copyright violations, and the ability to detect toxic content.
3.3 The Hybrid Validation Loop: LLM-as-a-Judge and Human-in-the-Loop Integration
Cogniview employs a hybrid validation approach that leverages the speed of automation while mitigating the known pitfallsofautomatedevaluation,suchasinheritedbias.
3.3.1 LLM-Judge Functionality
The platform uses proprietary or specialized fine-tuned LLM-Judges (like EasyJudge ) to perform rapid, large-scale, reference-freescoringofoutputsbasedonsubjectivecriteriasuchastone,style,andconciseness.Theseautomatedjudges providenear-instantfeedbackandbroadcoverageacrosshigh-volumeevaluationruns.
3.3.2 Human-in-the-Loop (HITL) Governance
Human domain experts are integrated into the loop to supervise the LLM-Judge functionality and ensure alignment with humanvalues.Thisisnotforbulkgrading,butforstrategicgovernance:
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
Criteria Definition: Experts meticulously vet and refine the evaluation criteria (which may span hundreds of criteria acrossdozensofscenariotypes).
Auditing Edge Cases: Human reviewers manually inspect ambiguous or low-scoring outputs flagged by the automated judge,providingfinalvalidation.
Bias Correction and Governance: Experts conduct longitudinal bias audits to ensure the LLM-Judge is not inheriting systemicbiasesandalignevaluationmechanismswithsocialintuitionandethicalexpectations.
ThearchitecturalchoicetoembedhumanexpertiseasamechanismforgovernanceandrefinementensuresthattheLLMJudge component is treated as an auditable system, preventing the over-reliance that could lead to unchecked bias propagation.
To synthesize the scores generated across these technically diverse domains (Capability, Operational, and Alignment), CogniviewutilizesaMulti-CriteriaDecisionAnalysis(MCDA)framework.
This framework moves beyond the limitations of single-metric leaderboards by allowing users to define the weighted importance of various criteria based on their specific application goals. For example, a team deploying a chatbot for customer support might assign a weight of 50% to Latency, 30% to Cost, and only 20% to Cognitive Capability (MMLU). Conversely,alegalresearchteammightassignaweightof60%toFactualConsistency/HallucinationRate,30%toMMLU, and only 10% to Latency. This configurable weighting scheme ensures that the platform delivers a final score that accuratelyreflectsthemodel’s fitness for purpose
The system design also recognizes the necessity of Micro-Detail Visualization for MLOps teams. While aggregated scores provide a high-level view, MLOps engineers need to understand why models differentiate in performance. Therefore, the architecture supports deep-dive visualization, allowing users to inspect individual predictions and automatically find Differentiating Subsets of data points where one model failed and another succeeded. This capability is essential for exploratoryanalysis,debugging,andguidinginteractivefine-tuningeffortstoimprovemodelrobustness.
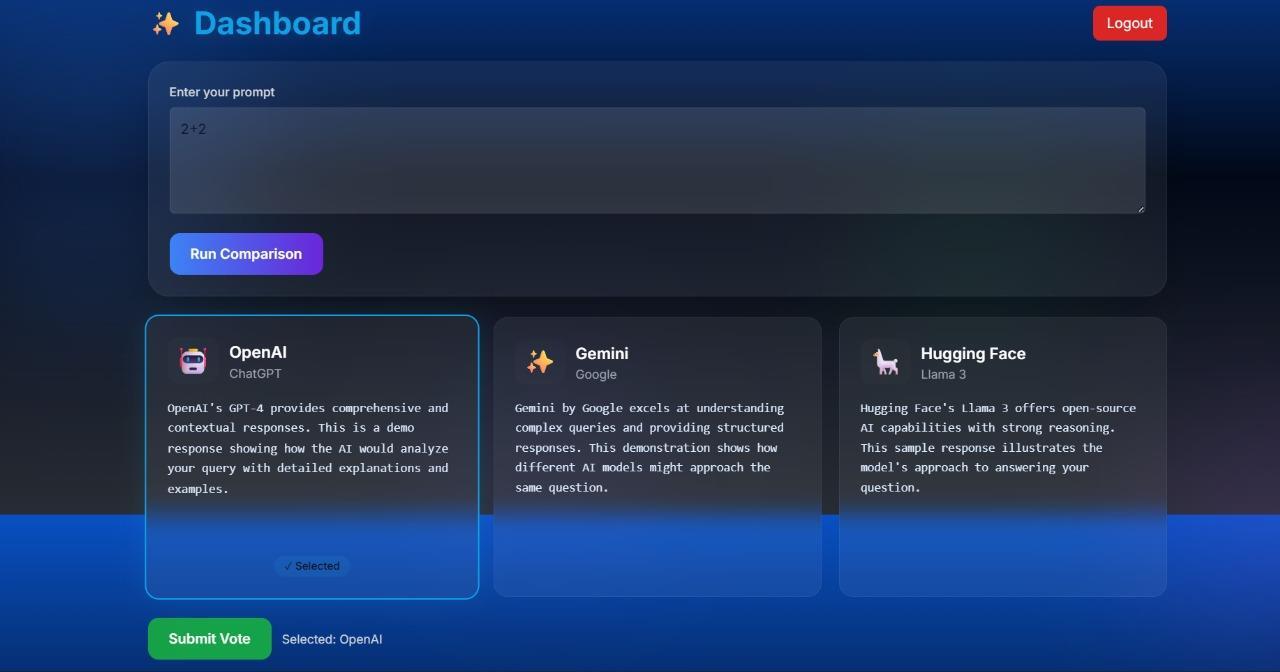
ThissectionpresentstheresultsobtainedfromcomparingresponsesgeneratedbyChatGPT,HuggingFace,andGeminifor a structured set of academic and general queries. The evaluation focuses on model performance, accuracy, clarity, completenessofresponses,andconsistencyacrossmodels.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
4.1 Model Performance
Table 1: Comparative Model Performance Across Evaluated AI Systems
Model
ChatGPT
HuggingFace
Gemini
Strengths
Provideswellstructured, clear, and easy-to-understand explanations.Goodat step-by-step reasoning.
Concise and directresponses,often well-organized and efficient.
Produces detailedanswerswith broader contextual information. Capable of citing multiple perspectives.
Weaknesses Overall Performance
Occasionally produces slightly generalized or simplifiedanswers.
Sometimes lacks depth and detailedreasoning.
At times includes unnecessary information, making responseslengthy.
Source: Conceptual evaluation of ChatGPT, Hugging Face, and Gemini responses.
4.2 Evaluation Metrics
Strong in clarity and explanationquality.
Balanced but mayrequirefollow-up questions for deeper understanding.
Strong in completeness, moderateinprecision.
Table 2: Multi-Dimensional Evaluation Metrics for ChatGPT and Gemini
of Explanation
Note: Ratings are qualitative assessments based on structured prompt evaluation.
4.3 Key Insights
Responses vary significantly across different AI models even for identical prompts.
ChatGPT provides the best balance between clarity and correctness,makingitreliableforconceptualunderstanding.
Hugging Face models are better suited for concise, direct answers,butsometimeslackdepth.
Gemini provides the most detailed responses,butattimesincludesirrelevantinformation.
AI-generated responses require human verification,especiallyforacademicorprofessionaluse.
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072 © 2026, IRJET | Impact Factor
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
5.1 Summary of Cogniview’s Contributions to Unified AI Evaluation
ThispaperpresentedtheconceptualdesignandmethodologicaljustificationforCogniview,aunifiedplatformaddressing the critical need for objective, multi-dimensional comparison of AI model responses in the complex modern MLOps landscape. By establishing an API Abstraction Layer to standardize inputs and outputs, and by integrating Capability, Operational Efficiency, and Alignment metrics, Cogniview provides a standardized, scalable, and transparent framework for model assessment. The implementation of the Hybrid Validation Loop, which leverages automated LLM-Judge speed alongside critical Human-in-the-Loop governance, provides high-coverage evaluation while maintaining ethical accountability. Finally, the use of MCDA scorecards and advanced visualization systems translates complex technical performancedataintoactionable,business-aligneddecisionmetrics,guidingeffectivemodelselectionanddeployment.
5.2 Critical
Although the Cogniview platform represents a significant methodological advancement, its implementation is subject to the inherent challenges of generative AI evaluation. The inherent subjectivity and potential for inherited bias within the LLM-as-a-Judgeparadigmrequiremandatory,continuoushuman oversightandlongitudinalbiasaudits.Furthermore,the reliability of academic benchmarks remains compromised, as models are frequently trained on the evaluation data. This necessitatesacontinuous,dynamicapproachtodatasetrefinementandadversarialtestingusing"in-the-wild"datasetsto ensurethattheplatformaccuratelymeasurestruegeneralizationcapabilitiesratherthanmeredatamemorization.
5.3
Future development of the Cogniview platform will focus on expanding its capacity to handle multi-modal inputs, integrating specialized metrics for evaluating image and audio generation quality (e.g., FID for image models ). Additionally, future work will concentrate on developing real-time performance monitoring agents capable of detecting modeldriftinproductionenvironmentsandfurtherautomatingthecontinuousrefinementfeedbackloopbetweenhuman evaluatorsandtheLLM-Judge'sscoringcriteria.
1. Ahmed, H., Traore, I., & Saad, S. (2017). Detection of online fake news using n-gram analysis and machine learningtechniques.
2. InternationalJournalofComputerApplications,172(1),1-10.Shu,K.,Sliva,A.,Wang,S.,Tang,J.,&Liu,H.(2017). Fakenewsdetectiononsocialmedia:Adataminingperspective.
3. ACM SIGKDD Explorations Newsletter, 19(1), 22-36. Wang, W. Y. (2017). "Liar, liar pants on fire": A new benchmarkdatasetforfakenewsdetection.
4. ProceedingsofACL,422-426.Zhou,X.,&Zafarani,R.(2018).Fakenews:Asurveyofresearch,detectionmethods, andopportunities.
5. arXivpreprintarXiv:1812.00315.Kaliyar,R.K.,Goswami,A.,&Narang,P.(2021).FakeBERT:Fakenewsdetection insocialmediawithaBERT-baseddeeplearningapproach.
6. Multimedia Tools and Applications, 80(8), 11765-11788. Ruchansky, N., Seo, S., & Liu, Y. (2017). CSI: A hybrid deepmodelforfakenewsdetection.
7. Proceedings of the 2017 ACM Conference on Information and Knowledge Management, 797-806. Singhania, S., Fernandez,N.,&Rao,S.(2017).3HAN:Adeepneuralnetworkforfakenewsdetection.
8. arXiv preprint arXiv:1705.09968. Perez-Rosas, V., Kleinberg, B., Lefevre, A., & Mihalcea, R. (2018). Automatic detectionoffakenews.
9. Proceedingsofthe27thInternationalConferenceonComputationalLinguistics,3391-3401.Potthast,M.,Kiesel, J.,Reinartz,K.,Bevendorff,J.,&Stein,B.(2018).Astylometricinquiryintohyperpartisanandfakenews.
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
10. arXiv preprint arXiv:1702.05638. Zhang, X., Ghorbani, A. A. (2018). An overview of online fake news: Characterization,detection,anddiscussion.
11. Information Processing & Management, 57(2), 102025. Wang, X., Hu, W., & Shu, K. (2020).Fake news detection onsocialmedia:Adataminingperspective.
12. ACMTransactionsonIntelligentSystemsandTechnology(TIST),11(3),1-27.OpenAI.IntroducingGPT-5.
13. OpenAIResearchBlog.Elisowski,M.(2024).7All-in-OneAIPlatformsthatLetYouTalktoMultipleModels.
14. Medium.EdenAI.BestGenerativeAIAPIs.
15. EdenAIBlog.GoogleCloud.VertexAI.
16. GoogleCloudDocumentation.GoogleCloud.EvaluateAImodelswithVertexAILLMComparator.
17. GoogleCloudBlog.EvidentlyAI.LLMEvaluationMetrics.
18. EvidentlyAIGuide.LabelStudio.HowtoBuildAIBenchmarksthatEvolvewithYourModels.
19. LabelStudioBlog.Anthropic.ChallengesinevaluatingAIsystems.
20. AnthropicResearchBlog.GalileoAI.LLMPerformanceMetrics.
21. GalileoBlog.FrugalTesting.BestPracticesandMetricsforEvaluatingLargeLanguageModels(LLMs).
22. FrugalTestingBlog.ArtificialAnalysis.Comparisonandrankingofover100AImodels.
23. ArtificialAnalysisLeaderboards.AllenAI.EvaluationFrameworks.
24. AllenInstituteforAI.OpenAI.(2024).WhatGDPvalmeasures.
25. OpenAIEvaluationsResearch.Jimenez,F.,etal.(2024).SWE-bench.
26. arXivpreprint.GenusofTechnology.EvaluatingGenerativeAI:AComprehensiveGuide.
27. Medium.(2025).QuantitativeMetricsforGenerativeModels.
28. arXivpreprintarXiv:2501.18897v1.MicrosoftAzure.GetstartedwithAI.
29. AzureAIDocumentation.EvidentlyAI.LLM-as-a-Judge.
30. EvidentlyAIGuide.(2024).EasyJudge:AMultidimensionalLLM-as-JudgePlatform.
31. arXivpreprintarXiv:2410.09775v1.EthicsND.CanWeTrustAItoJudge?
32. NotreDameEthicsInstitute.MicrosoftAzure.ModelBenchmarks(HarmBench,Toxigen).
33. AzureAIFoundryDocumentation.(2022).ComparativeEvaluationandComprehensiveAnalysis.
34. DataIntelligence.(2023).FairnessMetricsinAI.
35. MDPIAppliedSciences.Shelf.FairnessMetricsinAI.
36. ShelfBlog.Vectara.PublicLLMHallucinationLeaderboard.
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072 © 2026, IRJET | Impact Factor value: 8.315 | ISO 9001:2008 Certified Journal | Page4010
International Research Journal of Engineering and Technology (IRJET) e-ISSN: 2395-0056
Volume: 13 Issue: 04 | Apr 2026 www.irjet.net p-ISSN: 2395-0072
37. GitHub.Sainitesh,S.(2024).HowtoEnsureConsistentAIModelResponsesandValidateResultsUsingSemantic Kernel.
38. Medium.Sainitesh.MathematicallyEvaluatingHallucinationsinLLMs.
39. Medium.OpenAI.Whylanguagemodelshallucinate.
40. OpenAIResearchBlog.(2024).HaluEval-Wild:ABenchmarkforEvaluatingLLMHallucinationsintheWild.
41. arXivpreprintarXiv:2403.04307v1.GoogleCloud.VisualizingEvaluationReportsinVertexAI.
42. Google Cloud Documentation. Computer.org. (2025). Computational Framework for Comparative Analysis of HumanandAI-GeneratedPaintings.
43. IEEEComputerGraphicsandApplications.(2025).Visualizespecificpredictionmatches.
44. arXivpreprintarXiv:2502.14675v1.AlmaBetter.VisualizingandAnalyzingModelPerformance.
45. AlmaBetterBlog.Umbrello&VandePoel.(2021).FairAIFramework.
46. NationalInstitutesofHealth