Datasheet
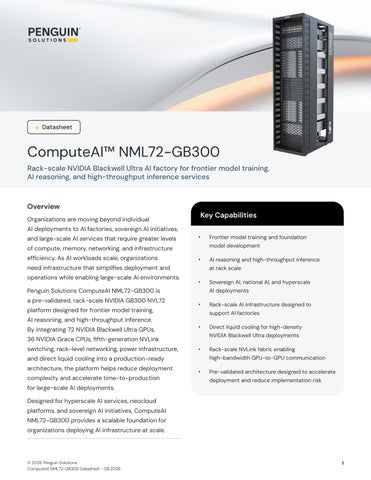
ComputeAI™ NML72-GB300 Rack-scale NVIDIA Blackwell Ultra AI factory for frontier model training, AI reasoning, and high-throughput inference services
Overview Organizations are moving beyond individual
Key Capabilities
AI deployments to AI factories, sovereign AI initiatives, and large-scale AI services that require greater levels
x
model development
of compute, memory, networking, and infrastructure efficiency. As AI workloads scale, organizations
x
need infrastructure that simplifies deployment and operations while enabling large-scale AI environments.
platform designed for frontier model training,
x
x
x
complexity and accelerate time-to-production
Direct liquid cooling for high-density NVIDIA Blackwell Ultra deployments
x
Rack-scale NVLink fabric enabling high-bandwidth GPU-to-GPU communication
and direct liquid cooling into a production-ready architecture, the platform helps reduce deployment
Rack-scale AI infrastructure designed to support AI factories
36 NVIDIA Grace CPUs, fifth-generation NVLink switching, rack-level networking, power infrastructure,
Sovereign AI, national AI, and hyperscale AI deployments
AI reasoning, and high-throughput inference. By integrating 72 NVIDIA Blackwell Ultra GPUs,
AI reasoning and high-throughput inference at rack scale
Penguin Solutions ComputeAI NML72-GB300 is a pre-validated, rack-scale NVIDIA GB300 NVL72
Frontier model training and foundation
x
Pre-validated architecture designed to accelerate deployment and reduce implementation risk
for large-scale AI deployments. Designed for hyperscale AI services, neocloud platforms, and sovereign AI initiatives, ComputeAI NML72-GB300 provides a scalable foundation for organizations deploying AI infrastructure at scale.
© 2026 Penguin Solutions ComputeAI NML72-GB300 Datasheet - 08.2026
1
Rack-Scale AI Infrastructure for Strategic AI Initiatives Organizations that are deploying larger models, serving more users, and building AI capabilities require greater performance, capacity, and infrastructure efficiency than traditional AI environments can provide. ComputeAI NML72-GB300 delivers rack-scale infrastructure designed to support strategic AI initiatives from frontier model development to production-scale AI services.
Build Differentiated AI Capabilities Organizations developing foundation models require massive-scale compute resources capable of supporting distributed model training and ongoing model development. ComputeAI NML72-GB300 provides the infrastructure required for frontier model training and proprietary model development, helping organizations build differentiated AI capabilities.
Enable Sovereign AI Initiatives Governments, research organizations, and national AI programs require dedicated AI infrastructure capable of supporting strategic AI development within controlled environments. ComputeAI NML72-GB300 combines rack-scale compute, networking, and infrastructure efficiency in a pre-validated platform that helps organizations to deploy and operate sovereign AI environments with greater confidence and scalability.
Deliver AI at Massive Scale Organizations deploying AI services at scale require infrastructure capable of supporting growing volumes of AI requests while maintaining responsiveness and throughput. ComputeAI NML72-GB300 combines 72 NVIDIA Blackwell Ultra GPUs, fifth-generation NVLink switching, and rack-scale architecture to support AI reasoning and inference for large-scale deployments, helping organizations expand AI services across users, applications, and business functions.
Optimize AI Service Economics As AI adoption grows, organizations require platforms capable of serving high volumes of AI requests efficiently. By combining high GPU density, direct liquid cooling, and an integrated rack-scale infrastructure, ComputeAI NML72-GB300 supports high-throughput inference environments that help improve infrastructure utilization and optimize the delivery of AI services at scale.
© 2026 Penguin Solutions ComputeAI NML72-GB300 Datasheet - 08.2026
2
Deployment-Ready Infrastructure for Large-Scale AI ComputeAI NML72-GB300 is a pre-validated rack-scale NVIDIA GB300 NVL72 platform designed to support frontier model training, AI reasoning, and high-throughput inference. By integrating compute, memory, networking, storage, power, cooling, and system management into a production-ready architecture, the platform helps organizations simplify deployment planning and accelerate time-to-production for large-scale AI infrastructure.
Validated L11 Rack-Scale Configuration Component
Validated Configuration
Platform
ComputeAI NML72-GB300 Rack-Scale AI Factory
GPU
72x NVIDIA Blackwell Ultra GB300 GPUs
GPU Memory
20.1 TB HBM3e (279 GB per GPU)
CPU
36× NVIDIA Grace CPUs
Host Memory
17.28 TB LPDDR5X
AI Fabric
5th Generation NVIDIA NVLink Rack-Scale Fabric
Network Fabric
36× NVIDIA ConnectX-8 SuperNIC Ports
DPU
18x NVIDIA BlueField-3 DPUs
Management Network
2× NVIDIA SN2201 Management Switches
Storage
276 TB NVMe Storage
OS Storage / Data Storage
34.6 TB NVMe SSD / 276.5 TB NVMe SSD
Cooling
Direct Liquid Cooling with Integrated Rack Manifold
Power
8× 33 kW Power Shelves, 48× 5.5 kW PSUs
Supported Operating System
Ubuntu 24.04 LTS (ARM64), RHEL 9.x (ARM64), Rocky Linux 9.x (ARM64)
Warranty
3-Year Standard Warranty*
* Final warranty terms per Penguin Solutions agreement
Contact Us For sales queries, please contact sales@penguinsolutions.com. To learn more about ComputeAI NML72-GB300 and other Penguin Solutions products, please visit: www.penguinsolutions.com © 2026 Penguin Solutions, Inc. All rights reserved. Penguin Solutions and ComputeAI are trademarks or registered trademarks of Penguin Solutions. All other product names, trademarks, and registered trademarks are the property of their respective owners. All company, product, and service names used in this document are for identification purposes only. Use of these names, trademarks, and brands does not imply endorsement.